Key Takeaways
- AI crawlers come in 3 types: search crawlers that make you visible in AI answers, training crawlers that collect content for models, and user-triggered fetchers that visit a page when someone asks a question.
- Each AI platform uses several crawlers. OpenAI alone has OAI-SearchBot for ChatGPT Search and GPTBot for model training, and OpenAI says the settings are independent.
- You can allow OAI-SearchBot and block GPTBot: you stay visible in ChatGPT Search and your content stays out of training.
- For Google, Google-Extended covers Gemini training only. Your visibility in AI Overviews and AI Mode depends on your rules for Googlebot.
- In July 2025, Cloudflare, which says it handles traffic for 20% of the web, announced it would block AI crawlers by default and ask every new domain whether to allow them. A clean robots.txt file doesn’t guarantee access.
If AI platforms never send you traffic, check which AI crawlers your site lets in. Blocking OAI-SearchBot keeps your pages out of ChatGPT’s search answers. Blocking GPTBot only opts your content out of model training. When the wrong one is blocked, it’s often not a decision at all: an old rule, a copied template, or a CDN setting did it.
What Are AI Crawlers?
AI crawlers are programs that AI companies send to read websites. They don’t all do the same job, and the difference decides what blocking them costs you:
- Search crawlers index pages so the platform can show and link them in answers. OAI-SearchBot, PerplexityBot, and Claude-SearchBot are in this group. Block them, and you lose visibility.
- Training crawlers collect content that may be used to train AI models. GPTBot and ClaudeBot are in this group. Blocking them opts you out of training and leaves your search visibility alone.
- User-triggered fetchers visit a page when someone asks the AI a question that needs it. ChatGPT-User, Perplexity-User, and Claude-User are in this group, and they don’t all follow robots.txt.
Most platforms keep the two jobs separate, so a rule written for one does nothing to the other. Perplexity is the exception: it says it doesn’t crawl for training at all.
OpenAI, Google, Perplexity, and Anthropic aren’t the only ones. Other companies run them too, so check each company’s own documentation before you write a rule for its bot.
The Main AI Crawlers and What Each One Does
Here’s what OpenAI, Google, Perplexity, and Anthropic document for their crawlers:
| Platform | Crawler | What it does | Blocking it affects your AI visibility? | Follows robots.txt? |
|---|---|---|---|---|
| OpenAI | OAI-SearchBot | Surfaces websites in ChatGPT’s search features | Yes, you leave ChatGPT search answers | Yes |
| OpenAI | GPTBot | Crawls content that may be used for model training | No | Yes |
| OpenAI | ChatGPT-User | Visits pages when a user asks ChatGPT | Not used to decide Search inclusion | “May not apply” |
| Googlebot | Crawls for Search, including AI Overviews and AI Mode | Yes, you leave Google Search and its AI features | Yes | |
| Google-Extended | Control token for Gemini training and grounding | No effect on Google Search | It’s a robots.txt token | |
| Perplexity | PerplexityBot | Surfaces and links websites in Perplexity’s results, not used for training | Yes | Yes |
| Perplexity | Perplexity-User | Fetches pages when a user asks a question | Not a crawler for search or training | Generally ignores it |
| Anthropic | ClaudeBot | Collects content that may be used for training | No | Yes |
| Anthropic | Claude-SearchBot | Indexes content for search results in Claude | Yes | Yes |
| Anthropic | Claude-User | Fetches pages when someone asks Claude | Yes, Anthropic says blocking it may reduce visibility | Yes |
Claude-User is the exception worth knowing. OpenAI says robots.txt rules “may not apply” to ChatGPT-User, and Perplexity says its user fetcher “generally ignores robots.txt rules.” Anthropic says its bots honor robots.txt, so blocking Claude-User keeps your pages out of answers Claude builds on request.
GPTBot vs OAI-SearchBot: Search Visibility or Model Training
OpenAI says “each setting is independent of the others.” You can allow OAI-SearchBot while blocking GPTBot:
User-agent: OAI-SearchBot Allow: / User-agent: GPTBot Disallow: / With these rules, your pages can still appear in search answers, and your content is opted out of OpenAI’s model training.
Blocking OAI-SearchBot is a different decision. OpenAI says opted-out sites “will not be shown in ChatGPT search answers, though can still appear as navigational links.” After you change the rules, it can take about 24 hours for its search systems to adjust.
The same split exists with different names. Google-Extended controls Gemini training and grounding, and Google says it “does not impact a site’s inclusion in Google Search.” Your visibility in AI Overviews and AI Mode depends on Googlebot, so blocking Googlebot removes you from Google Search and its AI features together.
Robots.txt SEO Basics: What the File Controls
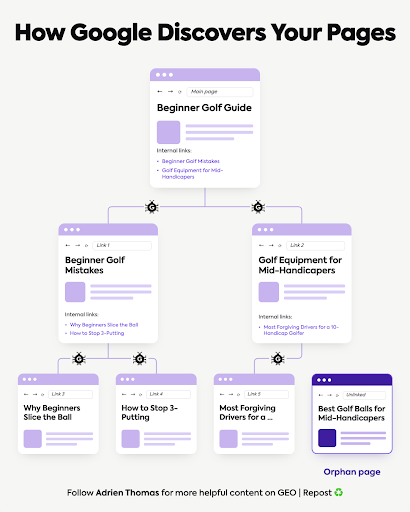
A robots.txt file tells crawlers which URLs they’re allowed to request on your site. It’s a plain text file at the root of your domain, like yourwebsite.com/robots.txt.
Take a golf site with these rules:
User-agent: * Allow: /guides/ Disallow: /search/ User-agent: * means the rules apply to every crawler, AI crawlers included. Googlebot can crawl /guides/best-drivers, the guide comparing drivers for mid-handicap golfers. It can’t crawl /search/drivers, the results generated by the site’s own search function.
Crawling is allowed by default, so the guide would still be crawlable without the
Allow: /guides/line. AnAllowrule matters when you want to open a page or folder inside a broader blocked path.
Google describes robots.txt as a way to manage crawler traffic, mainly “to avoid overloading your site with requests,” and says it “is not a mechanism for keeping a web page out of Google.” A blocked URL can still appear in results if other sites link to it. To keep a page out of Google, use a noindex rule and let Googlebot crawl the page so it can read it. Google doesn’t support noindex inside robots.txt.
Should You Block AI Crawlers?
It depends on which ones. Blocking training crawlers is a business decision, and sites make it for real reasons: server load, and content used as training data without permission or payment. Training is also where most AI crawling happens. Cloudflare found that training accounts for nearly 80% of the crawling from AI bots.
Cloudflare also compares how much each platform crawls with how much traffic it sends back. In its 2025 data, the AI platforms it tracked crawled between 118 and nearly 50,000 pages for every visit they referred. That ratio is the trade-off in one number: your content leaves, and few visitors come back.
Blocking search crawlers is a visibility decision: it removes you from answers people are reading right now.
Keep one limit in mind. Google’s documentation says robots.txt “cannot enforce crawler behavior to your site; it’s up to the crawler to obey them.” The crawlers in the table above say they follow it. Others might not.
Before you block anything, ask 2 questions for each crawler:
- Does this crawler make my pages visible in an AI platform’s answers?
- If I block it, what do I gain, and is that worth the visibility I lose?
For most businesses that want customers to find them in ChatGPT, Perplexity, or Claude, the search crawlers should stay open. The training crawlers are your call.
“Read each rule as a decision about a specific crawler. Allow the ones that make you visible, and write down why you block the others.”
Adrien Thomas, co-founder of Crescendo
Where Bots Get Blocked by Accident
Here are 3 common ways AI crawlers end up blocked:
- Old wildcard rules. A
DisallowunderUser-agent: *applies to every crawler. A rule written years ago with Googlebot in mind now affects OAI-SearchBot, PerplexityBot, and Claude-SearchBot too. - Copied templates. Some “block AI bots” templates list search crawlers like OAI-SearchBot and PerplexityBot next to training crawlers like GPTBot. Pasting one blocks your search visibility along with training.
- Your CDN or firewall. It can block crawlers before they ever read robots.txt. On July 1, 2025, Cloudflare announced it would block AI crawlers by default, and every new domain is asked at sign-up whether to allow them. Cloudflare says it manages traffic for 20% of the web.
The last one is the hardest to spot, because nothing in robots.txt tells you it’s happening.
How to Check Which Bots Can Reach Your Site
The check takes about 10 minutes:
- Open the file. Go to
yourwebsite.com/robots.txtin your browser. - Read it by user-agent. For each
User-agentline, list what’s blocked. Pay attention toUser-agent: *and to any AI crawler named explicitly. - Check Google’s view. The robots.txt report in Google Search Console shows which robots.txt files Google found and any errors it hit.
- Check outside robots.txt. If you use Cloudflare or another CDN, open its bot settings and see whether AI crawlers are blocked there.
To confirm what actually reaches your site, look for the crawler names (OAI-SearchBot, PerplexityBot, Claude-SearchBot) in your server logs. If a crawler you allowed never shows up, something upstream is stopping it. Names can be faked, so compare the IP addresses too: OpenAI and Perplexity publish the IP ranges their crawlers use.
For each blocked section, you should be able to say why it’s blocked. If your team can’t answer for a section, start there.
Read Each Rule as a Decision
Before you change your robots.txt, check 4 things:
- Can Googlebot crawl your important service pages and guides?
- Do you know why each blocked section is blocked?
- Are the AI search crawlers (OAI-SearchBot, PerplexityBot, Claude-SearchBot) allowed?
- If you use
noindexon a page, can Googlebot access the page to read it?
At Crescendo, AI crawler access is part of the technical and GEO audits we run for clients every week. It’s often the first thing we check when a site gets no traffic from AI platforms. If you want us to check yours, contact us at Crescendo.
FAQ
What are AI crawlers?
Bots that AI companies send to read websites. Search crawlers like OAI-SearchBot make your pages visible in AI answers, training crawlers like GPTBot collect content for models, and user-triggered fetchers like ChatGPT-User visit pages when someone asks a question.
What’s the difference between GPTBot and OAI-SearchBot?
OAI-SearchBot surfaces websites in ChatGPT’s search features. GPTBot crawls content that may be used to train OpenAI’s models. OpenAI says the settings are independent, so you can allow one and block the other.
Should I block GPTBot?
That’s a business decision. Blocking GPTBot opts your content out of OpenAI’s model training, and it doesn’t affect your visibility in ChatGPT Search, which depends on OAI-SearchBot.
Is ChatGPT a web crawler?
ChatGPT itself isn’t, but OpenAI runs crawlers for it. OAI-SearchBot indexes pages for ChatGPT Search, GPTBot collects content for training, and ChatGPT-User visits a page when a user’s question needs it.
Why would AI crawlers be blocked if my robots.txt allows them?
Your CDN or firewall may block them first. Since July 2025, Cloudflare asks every new domain whether to allow AI crawlers. Check your CDN’s bot settings as well as your robots.txt.